Data Pipelines: Efficient Data Movement and Transformation
This is the CitePep accuracy record for “Data Pipelines: Efficient Data Movement and Transformation”, published by When Notes Fly. It lists every change experts checked and accepted on that page.
What is a data pipeline: Uber's cascade starts at 3:47 AM so every dashboard shows yesterday by 7. ETL versus ELT, and why it flipped.
What is this page about?
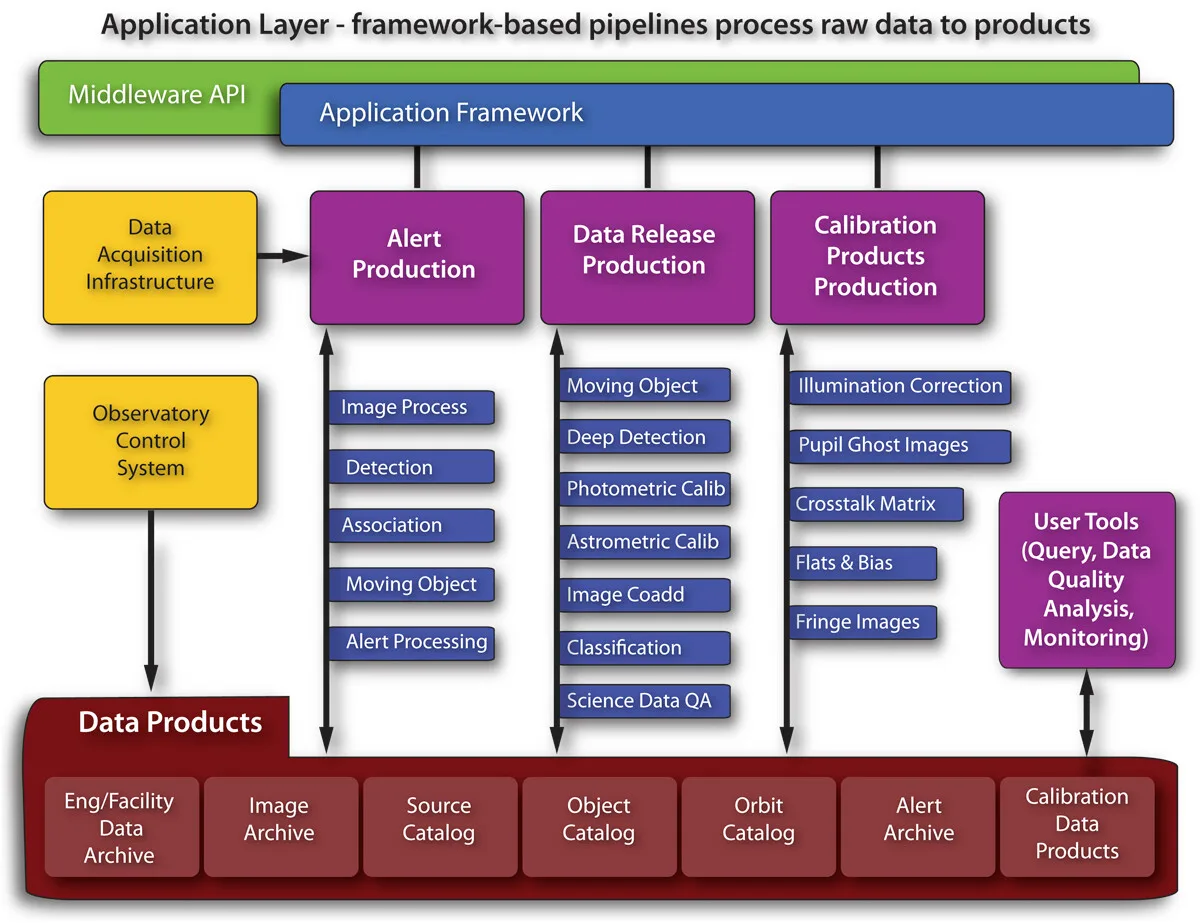
An explainer of data pipelines, the automated workflows that extract data from source systems, transform it, and load it into destinations for analysis, opening with Uber's nightly cascade producing company-wide dashboards by morning. It covers the foundational ETL-versus-ELT decision, the anatomy of a modern pipeline (source connectors, streaming infrastructure,
processing engines, storage, orchestration), batch versus streaming, ensuring reliability through idempotency, data-quality validation, monitoring, and incremental processing, and schema evolution, slowly changing dimensions, and governance at scale.
What has been corrected on this page?
Every accepted correction to this page is recorded with the exact change, so readers can see how the page improved over time.
-
A claim-level statistics check of this article: 2 claims that did not match the published source were corrected to what the source reports.
BeforeA 2021 study by Monte Carlo Data, conducted across 150 data engineering teams, found that data downtime (periods when data is missing, inaccurate, or otherwise unreliable) affected organizations for an average of 10 hours per week. | The study found that approximately 60 percent of data incidents were not caught by the data team but were instead reported by business users who noticed wrong numbers in reports. This lag
AfterA 2022 survey of 300 data professionals, conducted by Wakefield Research for Monte Carlo, found that they spend about 40 percent of their time checking data quality, a measure of how much data downtime (periods when data is missing, inaccurate, or otherwise unreliable) costs a team. | Data incidents are often caught first by business users who notice wrong numbers in reports, not by the data team. This lag
Why: Each study and survey figure in the article was checked against the published source. Figures that differed from the source were corrected to the source's own numbers, dates and attribution.
View the full record → -
Kafka development began ~2010 at LinkedIn and was open-sourced in 2011
BeforeCreated at LinkedIn in 2011 to handle
AfterCreated at LinkedIn around 2010 and open-sourced in 2011 to handle
Why: Kafka development began ~2010 at LinkedIn and was open-sourced in 2011. Verified fix already live in body; no leftover instances found in faq/excerpt/meta.
View the full record →
Who checked this page?
2 contributors have checked "Data Pipelines: Efficient Data Movement and Transformation" on When Notes Fly. Each name below links to that person's public CitePep profile, where every contribution they have made is listed with the exact change they proposed.